Cause: the shell session does not have the API key loaded. It happens when you open a new shell on Proxmox.
Fix: export it in that session with export LUDUS_API_KEY='<your-api-key>', or store it with the ludus apikey command. The key is shown by ludus-install-status when the installation finishes. Careful: running it again regenerates the key and the previous one stops working, so save it the first time. Do not paste it into chats or repositories.
GOAD stops before creating the VMs
Cause: Ludus needs the Debian 13 template for the router and it had not been built.
Fix:ludus templates build -n debian-13-x64-server-template and resume with the same instance (-i).
The SSH session drops and GOAD is left half done
Cause: the Ansible process dies with the session.
Fix: run it with nohup and a log file, and resume with -i <instance-ID> without creating another lab. See GOAD-Light.
SQL Server 2019 returns 404
Cause: the SQL Server Express 2019 installer download URL bundled with the mssql role no longer exists.
Fix: change the URL in ansible/roles/mssql/defaults/main.yml to Microsoft's official link (https://go.microsoft.com/fwlink/?linkid=866658) and check that it downloads the executable.
SSMS hangs on castelblack
Cause: the role downloads a small SSMS installer that now points to the SSMS 22 channel and hangs after detecting VS and .NET. Also, if you launch it over WinRM, the installer dies when the session closes.
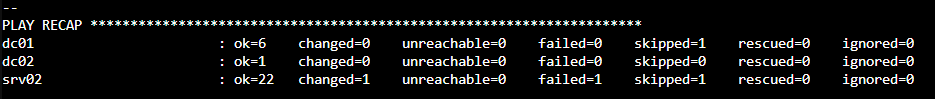
Ansible summary with a failure on srv02 (failed=1) during the SSMS installation
Fix:
Download the full SSMS 18.12.1 installer (about 677 MB) and leave it on the machine
Reboot to clear the pending restart
Run it as a scheduled task as SYSTEM, not from the WinRM session, with /install /quiet /norestart
Resume the remaining playbooks: servers.yml, security.yml and vulnerabilities.yml
After that, GOAD finished with failed=0 on all three machines.
Elastic runs out of memory
Cause: with 8 GB, Elasticsearch, Kibana and Fleet start very tight and Kibana stops responding during startup.
Fix: raise the VM to 12 GB of RAM, add 4 GB of swap and rerun only the Elastic role. Even so it is tight, with about 9 GB in use.
Events show up 6 hours off
Cause: the three Windows hosts had the Eastern time zone (UTC-4), but Proxmox gives them Madrid local time. Windows computed UTC +6 h. On top of that, DC01 took its time from the "Local CMOS Clock" and spread the error to DC02 and SRV02.
Fix:
Set the correct time zone (Romance Standard Time) on the three VMs
Point DC01 to an external NTP server, with w32time configured as a reliable source
DC02 syncs with the domain and SRV02 with DC01
Events from before the fix stay shifted. To see them cleanly, set the time picker to Last 15 minutes, which ends at "now" and excludes events dated in the future.
Proxmox rebooted and the lab does not respond
Cause: the GOAD VMs do not start on their own with the host.
Fix: power on the range with Ludus (check ludus power --help) or from Proxmox, and check that the Elastic agents are Healthy again in Fleet.
Installing NetExec on WSL fails
Cause: the build tools are missing (netifaces needs C and arc4/aardwolf need Rust).